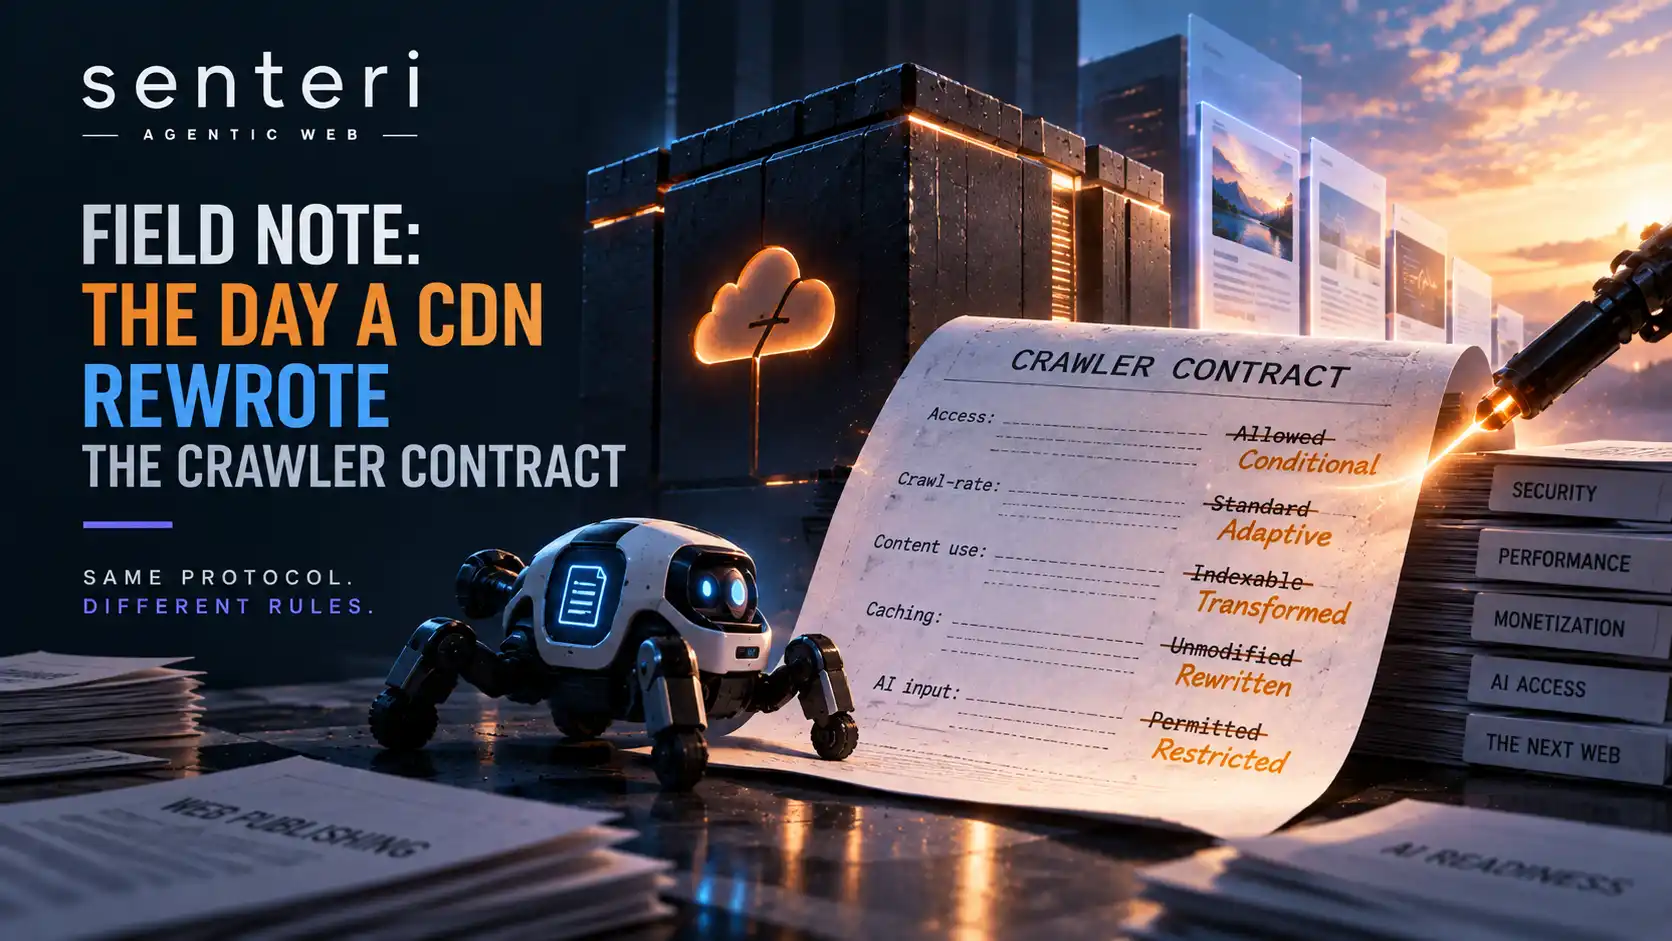
15 September 2026 — observations on Cloudflare's Accountable designation, and what it can and cannot enforce.
The constraint nobody could design around
For thirty years, crawler preferences lived in a text file. robots.txt is a declaration: it states what you want, after which the crawler decides whether to honour it. Enforcement was social.
A network sitting in front of the request can do something categorically different. It can state the preference, identify the visitor, classify the behaviour, and turn away whatever ignores it. That is a stronger instrument, but it comes with a limitation that turned out to be the whole story of this quarter.
A preference file can separate purposes after the fetch. A network cannot separate them during it.
Googlebot, Applebot and Bingbot crawl for search indexing and for model training under one identity. At the edge, a request either passes or it does not. You cannot admit half a crawler. So a site owner blocking training on Cloudflare was, mechanically, blocking search discovery too — which is why almost nobody did it, and why the July ultimatum was structurally unenforceable against the operator it most wanted to reach.
The secondary effect is the one worth recording. Operators that split their crawlers honestly — OpenAI, Anthropic, Perplexity — became individually addressable, and therefore individually blockable. The operator that did not split remained too costly to block. Legibility was penalised.
What shipped
Two things, on the day the new defaults went live.
Disallow AI Training. Available on every plan. It refuses model training while keeping the site fully indexed. The name is literal: Bot Preference Sync writes the corresponding Disallow directive into the site's robots.txt. Note what this means architecturally — the network layer did not replace the declarative layer, it started driving it. The edge enforces where it can and publishes a preference where it cannot.
The Accountable designation. A mixed-use crawler retains search access under Disallow AI Training only if Cloudflare labels it Accountable. Four qualifying conditions, met or committed to with a date:
- a training opt-out via
robots.txtor an equivalent standard - an opt-out from AI summaries, set with the operator now and through Cloudflare next year
- URL-level visibility into which pages were made available for training, plus metrics on how content surfaced in search
- an assurance that declining training does not affect ordinary search rankings
Apple, Google and Microsoft qualify. Amazon, Anthropic, Meta and OpenAI appear on the list for a different reason: they already run separate search and training crawlers, so their training-only bots are simply blocked when the setting is on.
Alongside this, the single "Block AI Bots" switch became three domain-level controls — Search, Training, Agent — and Block / Block on pages with ads now reach mixed-use crawlers, which they previously spared precisely because blocking them cost discoverability.
Reading the compliance closely
The four conditions are not uniformly satisfied today, and the difference matters for anyone measuring.
Google has offered Google-Extended since 2023, plus a control for excluding content from generative results. Apple has Applebot-Extended and a public statement that declining training does not affect ranking. Microsoft currently supports training preferences through a meta tag and is building domain-level no training support in robots.txt, targeted for early 2027.
So one of the three Accountable operators is compliant by commitment rather than by capability, and the qualifying bar explicitly permits that. This is not concealed — Cloudflare says so directly — but it changes what the designation certifies. It certifies a negotiated trajectory, not a present state.
What this is and is not
It is a better lock. It is not a new contract.
The old arrangement was: you crawl me, you send readers back. The first randomised study of AI summaries, run in early 2026 across roughly a thousand Chrome users and some seventy thousand searches, put the click loss to publishers near forty percent. Radar data from mid-year shows the same asymmetry from the traffic side: traditional search crawlers fetch a handful of pages per referral sent; AI crawlers fetch hundreds or thousands.
None of that is addressed by a setting that says no. The instrument that would address it — Pay Per Use, successor to Pay Per Crawl, paying when content actually contributes to an answer rather than when a file is fetched — currently has two launch partners. That is a pilot, not a market.
What we are watching next
Four measurable things, on our own logs and anyone else's willing to share:
- Migration fidelity. Existing
BlockandBlock on pages with adsselections under Training migrate toDisallow AI Training. Whether that migration is clean is an empirical question, and 403s to Googlebot are the cheap test. - Whether the training opt-out is honoured off-network. The edge can enforce for sites behind it. The
robots.txtdirective it publishes travels everywhere. The second one is the interesting number. - Whether Accountable status is ever revoked. A designation with no observed enforcement against a qualifying operator is a badge, not a standard. The first revocation, or the absence of one by mid-2027, will tell us which.
- The AI-summaries control. Today it is a binary set separately with each operator. Cloudflare's stated goal is granular control in one place by early next year. Consolidating that is harder than consolidating training, because summaries are a consumption behaviour, not a fetch.
The uncomfortable part
The terms of access to a meaningful fraction of the web changed this week through a configuration default, negotiated privately between one infrastructure company and four or five model operators.
The outcome happens to favour the party with the least leverage, which is why it is easy to applaud. But the mechanism is indifferent to who it favours. It worked because one company sits in front of enough traffic to make a default binding, and that property does not depend on the default being good.
Private infrastructure moved faster here than any regulatory process would have. That is worth noting plainly, without treating speed as proof of legitimacy. They are different questions, and only one of them was settled on 15 September.
SENTERI field notes track how machines read the web. Corrections and contrary log data are welcome.